Convert JSON to CSV: nested objects, arrays and Excel gotchas
· 7 min read · Updated · By Amir Badi
A flat list of JSON objects turns into CSV with one line of code in any language. The JSON you get from an API is rarely flat, though, and the CSV tends to land in Excel, which has its own opinions about your data. So you have two jobs: get the nested JSON into rows and columns, then get those rows into a spreadsheet with the zeros, digits and dates intact.
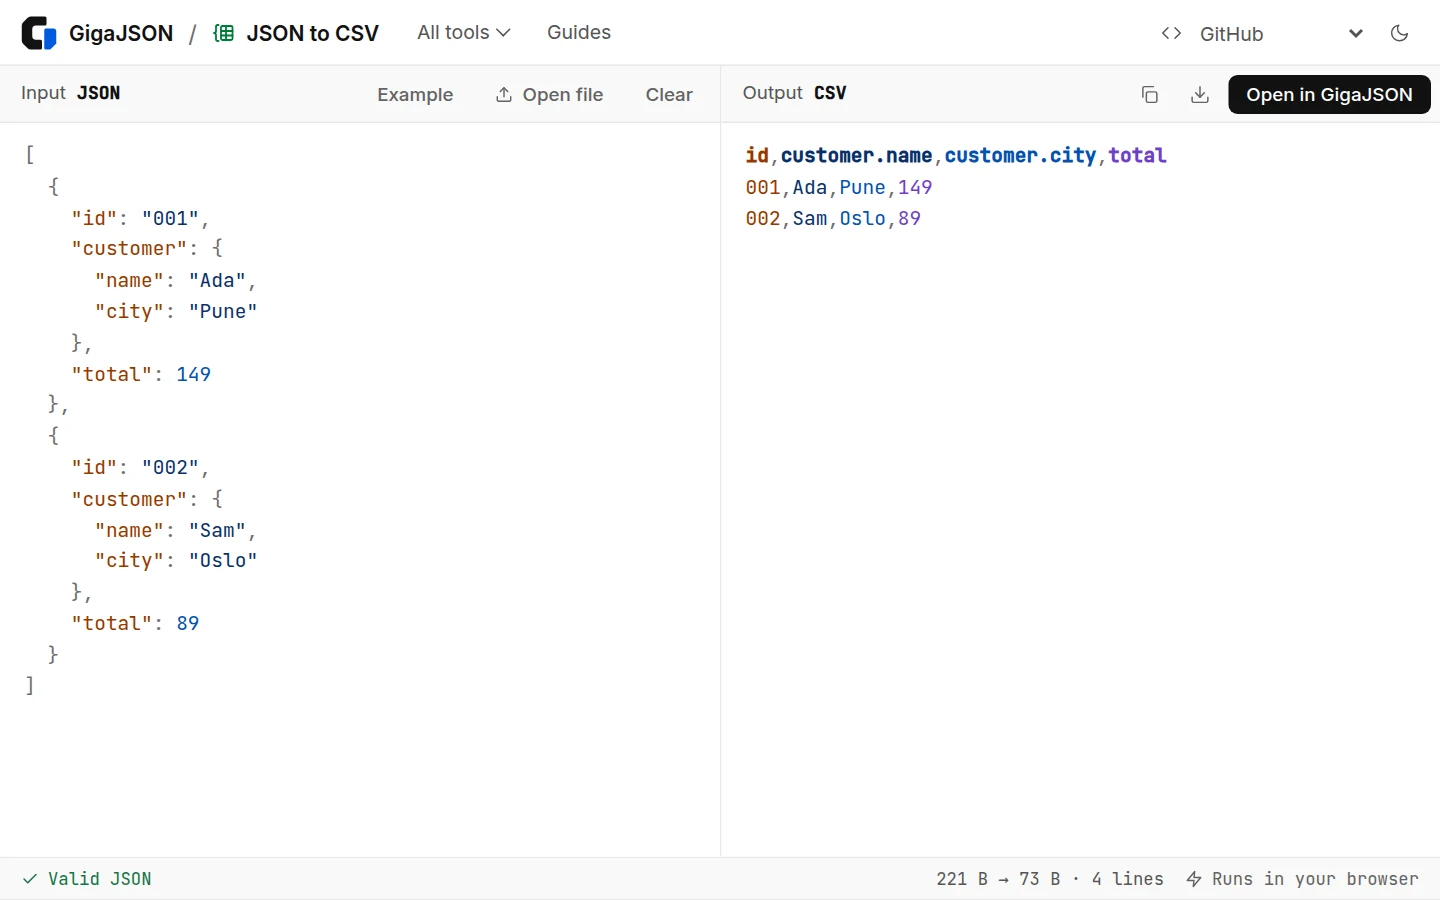
For a quick conversion, paste or open the file in the JSON to CSV converter. Below you'll find the choices it makes, and how to make different ones in code.
Decide what a row is
A CSV is one table, so first decide what one row stands for. Take this export:
[
  { "id": "00417", "name": "Ana Silva", "address": { "city": "Porto", "zip": "4000-123" },
    "tags": ["admin", "beta"], "signup": "2026-03-04", "card": "4111111111111111" },
  { "id": "00418", "name": "Ben \"Benny\" Ott", "address": { "city": "Austin" },
    "tags": [], "signup": "2026-03-05", "note": "=1+1" }
]
One row per user seems natural. If you want to know which users have which tags, though, one row per user and tag works better. Both are valid CSVs of the same JSON, and a converter can't choose for you. Most of the hard cases in JSON-to-CSV come back to this choice.
Nested objects become dotted columns
Objects inside a row are easy. Flatten them into columns named after their path:
| id | name | address.city | address.zip |
|---|---|---|---|
| 00417 | Ana Silva | Porto | 4000-123 |
| 00418 | Ben "Benny" Ott | Austin |
Watch two details. Rows can have different keys (Ben has no zip, Ana has no note), so build the column list from every row, not from the first. And pick a separator that can't appear in your keys. People usually pick a dot; if your keys contain dots, use / or __.
What to do with arrays
Converters disagree about arrays, and each choice has a cost.
Join them into one cell. ["admin","beta"] becomes admin;beta, which reads and filters well in a spreadsheet, but an empty list now looks like a missing one. I use this for short lists of plain values like tags.
Keep them as JSON text. The cell holds ["admin","beta"]. You lose nothing and can convert back, but Excel users will find it awkward. It suits arrays of objects you don't need to analyse.
Explode them into rows: one row per element, with the parent's fields repeated, so each order item carries its order ID. Pick this for line items, events and anything you'll sum or pivot. A record with several unrelated arrays gets one CSV per array, linked by ID, like tables in a database.
Some tools create numbered columns instead (tags.0, tags.1). Fine for fixed-length arrays such as coordinates. Anywhere else it gets messy: one record with 40 tags gives everyone 40 columns.
With jq
jq's @csv formats an array as a CSV line and handles the quoting. It refuses objects, and that's the first error most people run into:
$ jq -r '(.[0] | keys_unsorted) as $k | $k, (.[] | [.[$k[]]]) | @csv' users.json
jq: error (at users.json:6): object ({"city":"Po...) is not valid in a csv row
Name the columns you want and it works every time:
jq -r '["id","name","city","zip","tags"],
  (.[] | [.id, .name, .address.city, .address.zip, (.tags | join(";"))])
  | @csv' users.json
"id","name","city","zip","tags"
"00417","Ana Silva","Porto","4000-123","admin;beta"
"00418","Ben ""Benny"" Ott","Austin",,""The doubled quotes around Benny are correct CSV escaping. Missing values come out as empty cells.
To flatten everything without listing columns, build dotted keys from paths:
jq -r '
map([paths(scalars) as
| {key: ( | map(tostring) | join(".")), value: getpath()}]
| from_entries)
| (map(keys_unsorted) | add | unique) as
| , (.[] | [.[[]]])
| @csv' users.jsonYou get address.city, address.zip and also tags.0, tags.1 (numbered columns), sorted alphabetically because unique sorts. Empty arrays and objects vanish, since paths(scalars) visits only leaf values.
Exploding an array into rows is short in jq (if the syntax is new, jq vs JSONPath vs JMESPath walks through it):
jq -r '["order_id","sku","qty"],
(.orders[] | .id as | .items[] | [, .sku, .qty])
| @csv' orders.jsonWith Python
Python's standard library covers it. This version keeps columns in the order it first sees them and stores arrays as JSON text:
import csv
import json

def flatten(obj, prefix=""):
    out = {}
    for key, value in obj.items():
        name = f"{prefix}{key}"
        if isinstance(value, dict):
            out.update(flatten(value, name + "."))
        elif isinstance(value, list):
            out[name] = json.dumps(value, ensure_ascii=False)
        else:
            out[name] = value
    return out

with open("users.json", encoding="utf-8") as f:
    rows = [flatten(r) for r in json.load(f)]

columns = list(dict.fromkeys(k for r in rows for k in r))
with open("users.csv", "w", newline="", encoding="utf-8-sig") as f:
    writer = csv.DictWriter(f, fieldnames=columns)
    writer.writeheader()
    writer.writerows(rows)
Two of those lines are there for Excel. newline="" stops blank lines between rows on Windows. encoding="utf-8-sig" writes a byte order mark that tells Excel the file is UTF-8. Leave it out and Excel on Windows will often show é where you wrote é.
In pandas, json_normalize flattens and record_path explodes:
import json
import pandas as pd

with open("orders.json", encoding="utf-8") as f:
    data = json.load(f)

items = pd.json_normalize(
    data["orders"],
    record_path="items",
    meta=["id", ["customer", "name"]],
)
items.to_csv("order_items.csv", index=False, encoding="utf-8-sig")
sku,qty,id,customer.name
KB-01,1,A-100,Ana
MS-02,2,A-100,AnaCareful when you read it back: pd.read_csv("users.csv") also turns 00417 into 417. Pass dtype=str (or a per-column dict) for ID columns.
Excel gotchas
Your CSV can be perfect and still look wrong in Excel. Double-click it, and Excel guesses each column's type and gets these wrong:
| In the CSV | Excel shows | Why |
|---|---|---|
00417 |
417 |
looks like a number, zeros dropped |
4111111111111111 |
4.11111E+15, last digit becomes 0 |
Excel keeps 15 significant digits |
1E5 (a part number) |
1.00E+05 |
read as scientific notation |
3-4, MARCH1 |
a date | anything date-like is converted |
2026-03-04 |
a date in your local format | usually fine, but no longer text |
=1+1 |
2 |
cells starting with =, +, - or @ can be read as formulas |
é |
é |
UTF-8 read as the local code page (no BOM) |
one column of a;b;c |
everything in column A | your locale expects ; as the separator |
Ways to stop it, most reliable first:
- Don't double-click. Use Data > From Text/CSV (Get Data), set File Origin to UTF-8, and set ID-like columns to Text before loading. Excel then keeps what's in the file.
- In recent Microsoft 365 versions, File > Options > Data > Automatic data conversion lets you switch off the zero-stripping, the 15-digit cut, scientific notation and date conversion. That setting lives on your machine, so whoever you send the file to still gets the damage.
- Write
.xlsxinstead of CSV when the file is for Excel users. A library like openpyxl or pandas'to_excelstores text as text, so nothing is guessed. Without code, JSON to Excel writes the .xlsx in your browser: text stays text, numbers with more than 15 digits are kept as text, and a cell starting with=is never run as a formula. - Google Sheets has the same behaviour; when importing, untick "Convert text to numbers, dates, and formulas".
Cells that look like formulas are a security problem too. If users wrote the data (names, comments, support tickets), a value like =HYPERLINK(...) turns into a live formula when someone opens the CSV. Security people call this CSV or formula injection. When you export untrusted data for spreadsheets, put a single quote in front of any cell starting with =, +, -, @, a tab or a carriage return, as OWASP recommends.
Writing ="00417" into the CSV does keep the zeros in Excel. Every other tool then reads the literal text ="00417", so only do it when Excel is the sole reader.
In the browser
GigaJSON's JSON to CSV tool flattens nested objects into dotted columns (address.city) and keeps arrays inside a row as JSON text. It collects columns from every row in first-seen order and quotes what needs quoting. Hand it an object holding a single list ({"results": [...]}) and it uses that list as the rows. It runs in your browser, so your file stays put, and it copes with files of hundreds of megabytes. It doesn't add a byte order mark or escape formula characters. For Excel, use the From Text/CSV import above, and be careful with data users typed in.
To explode an array or pick columns first, open the file in the app. The Table view shows a list of objects as a grid you can sort and filter, and the Query tab selects the part you want before you export. For the reverse trip, CSV to JSON keeps values like 007 as text.
A checklist before you send the CSV
- Decide what one row means, and explode arrays you need to count or sum.
- Build the column list from every record, not the first.
- Keep IDs, ZIP codes, phone and card numbers as text all the way through.
- Write UTF-8 with a BOM if the file goes to Excel on Windows.
- Escape leading
=,+,-and@in user-provided values. - Open the result the way the recipient will, and look at the ID column.