How to view and query API responses and NDJSON logs
· 7 min read · Updated · By Amir Badi
The JSON you read on a normal workday mostly comes from two places: API responses in a terminal, and logs with a JSON object on every line. Machines write both easily, and people find both a pain to read raw. These are the commands I use for each, and what I do when the output outgrows the terminal.
I tested every command here with curl and jq 1.7.
Part 1: API responses
Pretty-print a response
curl -s https://api.example.com/orders | jq .-s hides curl's progress bar, which would otherwise get mixed into the output. If jq says parse error: Invalid numeric literal at line 1, column 9, look at what came back. It's often an HTML error page, or you passed -i and jq is trying to read the HTTP headers.
Keep the headers, but separately
You need the headers when debugging (status, rate limits, caching, content type), but jq can't parse them. Write them to a file of their own:
curl -sS -D headers.txt -o body.json https://api.example.com/orders
head -3 headers.txt
jq '.orders | length' body.json
Or print just the status code and timing after the body is saved:
curl -s -o body.json -w '%{http_code} %{time_total}s\n' https://api.example.com/ordersSave the body to a file anyway. You can then query it ten times without calling the API ten times.
Pull out what you need
These jq filters cover most of my API work:
jq 'keys' body.json                                   # what's at the top level
jq '.orders[0]' body.json                             # one record, to see the shape
jq -c '.orders[] | {id, status, total}' body.json     # a few fields per record
jq '[.orders[] | select(.status == "pending")] | length' body.json
jq -r '.orders[] | [.id, .status] | @tsv' body.json   # tab-separated, for column/sort/awk
-c prints one compact line per result, handy when you pipe into grep, sort or wc -l. -r prints strings without quotes.
JSON inside a JSON string
Webhooks, message queues and some logging setups wrap a JSON payload as a string inside another JSON object:
{"event": "webhook", "payload": "{\"event\":\"paid\",\"id\":\"A-100\"}"}fromjson parses it:
jq '.payload | fromjson' event.json{"event": "paid", "id": "A-100"}Paginated APIs
Save each page, then merge. If every page has a results array:
jq -s '[.[].results[]]' page*.json > all.json      # one array
jq -c '.results[]' page*.json > all.ndjson         # or one record per line
In the browser
For a response your own app made, open DevTools: Network tab, click the request, then Preview for a collapsible tree or Response for the raw text. Right-click the request for "Copy response", or "Copy as cURL" to replay it in a terminal.
DevTools slows down on large responses, and you lose the tree when you reload. For a big response, or one you want to keep, paste it into a viewer. GigaJSON takes the body alone or the whole output of curl -i (status line, headers and body). It recognises an HTTP response and opens it as an object with status, headers and a parsed body. The New document dialog also has a From URL tab. It sends a plain GET from your browser, so it works only for APIs that allow cross-origin requests (CORS) and need no auth headers.
Part 2: NDJSON logs
What NDJSON is
NDJSON (newline-delimited JSON), also called JSON Lines or JSONL, is one JSON value per line:
{"ts":"2026-09-30T10:00:01Z","level":"info","msg":"request","path":"/api/orders","status":200,"ms":42}
{"ts":"2026-09-30T10:00:02Z","level":"error","msg":"request","path":"/api/orders/17","status":500,"ms":913,"err":"db timeout"}
{"ts":"2026-09-30T10:00:02Z","level":"warn","msg":"slow query","ms":1204,"query":"SELECT ..."}
not json: panic recovered
{"ts":"2026-09-30T10:00:03Z","level":"error","msg":"request","path":"/api/users","status":502,"ms":30010,"err":"upstream"}
{"ts":"2026-09-30T10:00:04Z","level":"info","msg":"webhook","payload":"{\"event\":\"paid\",\"id\":\"A-100\"}"}
The file as a whole isn't valid JSON, and it doesn't have to be. A program can write, read or drop each line on its own, so structured loggers, data exports and log shippers all like the format. Line four is realistic too: a crash message or stack trace that went around the structured logger.
Filter by level (and why jq stops halfway)
You'd start with:
jq -c 'select(.level == "error")' app.ndjson{"ts":"2026-09-30T10:00:02Z","level":"error",...,"err":"db timeout"}
jq: parse error: Invalid numeric literal at line 4, column 4jq reads the lines in order and gives up at the first one that isn't JSON. You lose everything after line 4, the second error included, and the parse error is easy to overlook at the bottom of a long output. In a real log that bad line might sit at 3 a.m., and you'd never search the rest of the night.
Read each line as raw text (-R) and parse it with fromjson?. The ? drops lines that fail:
jq -cR 'fromjson? | select(.level == "error") | {ts, path, status, err}' app.ndjson{"ts":"2026-09-30T10:00:02Z","path":"/api/orders/17","status":500,"err":"db timeout"}
{"ts":"2026-09-30T10:00:03Z","path":"/api/users","status":502,"err":"upstream"}To find the lines that aren't JSON, so you know what you skipped:
awk '!/^[[:space:]]*\{/ { print NR": "$0 }' app.ndjsonThat prints 4: not json: panic recovered. It only checks that a line starts with {, which is enough to catch stray text.
Count, group and rank
To count entries per level in one pass, without loading the file into memory:
jq -nR 'reduce (inputs | fromjson?) as $l ({}; .[$l.level] += 1)' app.ndjson{"info": 2, "error": 2, "warn": 1}-n with inputs reads lines one at a time into reduce, so this works on logs far bigger than RAM.
Finding the slowest requests means sorting, and sorting needs every value at once. -s (slurp) collects the stream into an array:
jq -cR 'fromjson? | select(.ms != null)' app.ndjson \
| jq -s -c 'sort_by(-.ms) | .[:2] | map({path, ms})'[{"path":"/api/users","ms":30010},{"path":null,"ms":1204}]Slurping holds everything in memory. A few hundred MB is fine. Past that, filter first so you only slurp the lines you need.
Make it readable as columns
jq -rR 'fromjson? | [.ts, .level, .msg, (.status // "")] | @tsv' app.ndjson | column -t -s $'\t'.status // "" fills the gap where a line has no status, so the columns stay aligned.
Live tailing, compressed logs and big files
tail -f app.ndjson | jq -cR --unbuffered 'fromjson? | select(.status >= 500)'
zcat app.ndjson.gz | jq -cR 'fromjson? | select(.status >= 500) | .path'
grep '"level":"error"' app.ndjson | jq -c '{ts, path}'
--unbuffered makes jq print each match at once, which you need when its output feeds another pipe. The grep line speeds up large logs: grep throws away non-matching lines far faster than jq can parse them. It relies on how your logger writes JSON (spacing after colons, key order), so use it as a pre-filter and keep the real condition in jq.
Python, when the logic grows
import json
from collections import Counter

levels = Counter()
with open("app.ndjson", encoding="utf-8") as f:
    for n, line in enumerate(f, 1):
        try:
            entry = json.loads(line)
        except json.JSONDecodeError:
            print(f"line {n}: not JSON")
            continue
        levels[entry.get("level")] += 1
print(levels.most_common())
Reading line by line keeps memory flat, and you get the line number of each bad entry, which jq won't give you.
Convert between NDJSON and JSON
jq -s . app.ndjson > app.json      # NDJSON to one array (all lines must be valid)
jq -c '.[]' app.json > app.ndjson  # array back to NDJSON
The JSON Lines to JSON tool does the first conversion in the browser, and JSON to JSON Lines the second.
Looking at logs instead of grepping them
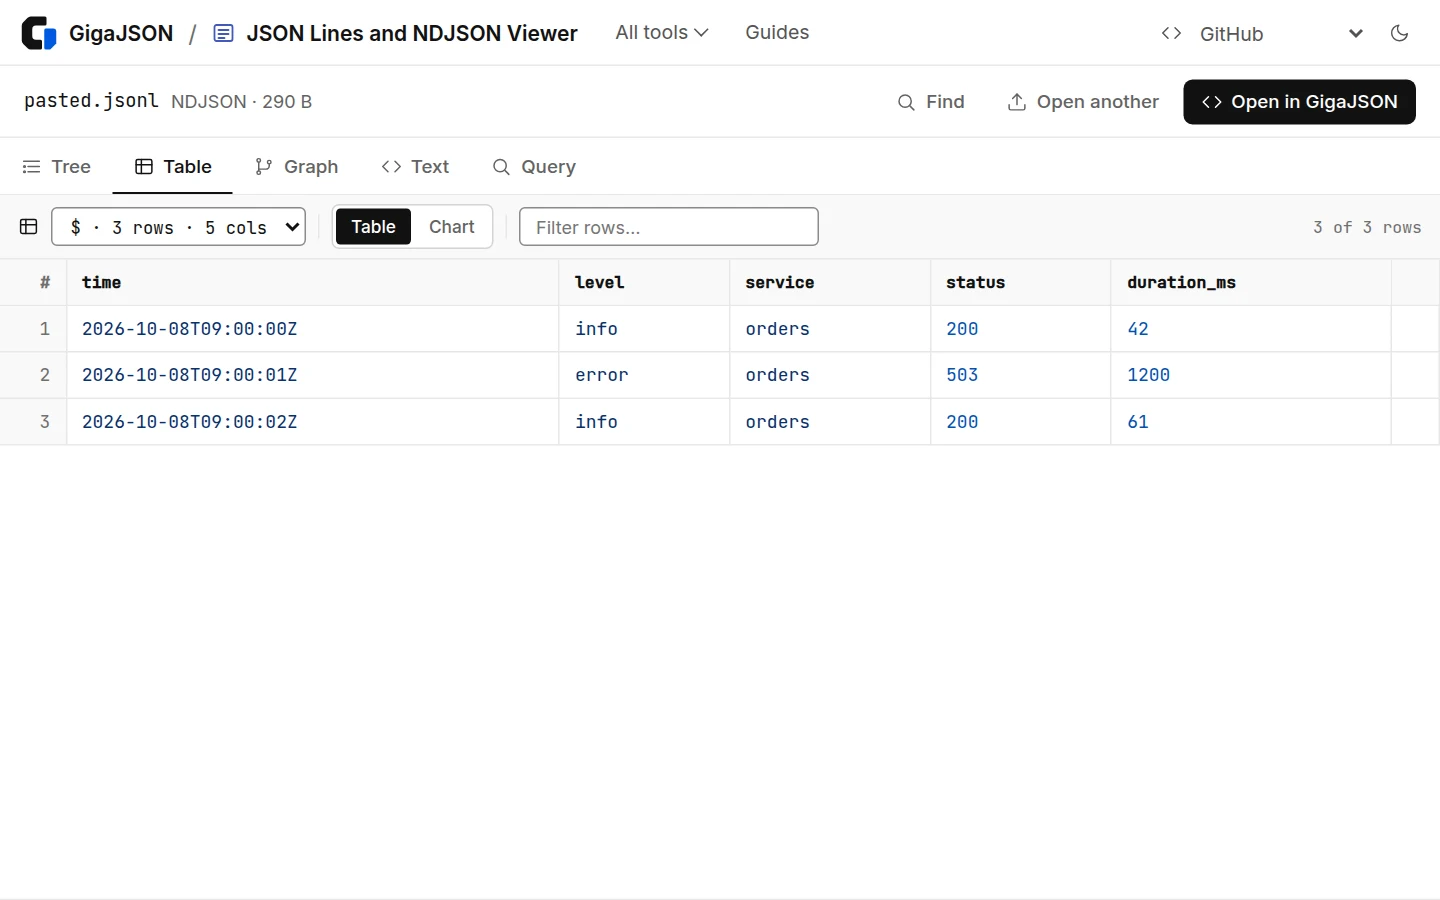
Sometimes you don't know what you're after yet. Which fields exist? What does an odd entry look like? Is status always a number? A table answers those faster than a terminal. GigaJSON opens .ndjson and .jsonl files as a list with one item per line. The Table view gives each field a column you can sort and filter, and the Inspector lists the most common values of the selected field across the first 10,000 entries. The Query tab runs JSONPath or JMESPath over the whole log, for example $[?(@.status >= 500)]. A worker in your browser does the parsing, so a log of a few hundred megabytes won't freeze the page, and the file stays on your machine.
Two limits. Strip the non-JSON lines first (the jq -cR 'fromjson?' command above writes a clean copy), because one broken line stops the file from opening as NDJSON. And jq in the browser takes inputs up to about 20 MB. For bigger logs, use JSONPath or JMESPath there, or jq on the command line. Files over a few hundred MB are covered in how to open a large JSON file.
A short cheat sheet
| Task | Command |
|---|---|
| Pretty-print a response | curl -s URL | jq . |
| Body and headers apart | curl -sS -D headers.txt -o body.json URL |
| Parse a JSON string field | jq '.payload | fromjson' |
| Merge pages | jq -s '[.[].results[]]' page*.json |
| Filter a log, skip bad lines | jq -cR 'fromjson? | select(.level == "error")' app.ndjson |
| Count per field value | jq -nR 'reduce (inputs | fromjson?) as $l ({}; .[$l.level] += 1)' |
| Follow a live log | tail -f app.ndjson | jq -cR --unbuffered 'fromjson? | select(...)' |
| NDJSON to array | jq -s . app.ndjson |
To try these filters on your own data without installing anything, paste it into the jq playground, or open it in the app for the tree, table and query views.