How to open a large JSON file (100 MB to 1 GB) without crashing
· 8 min read · Updated · By Amir Badi
You download an export, a log dump or an API backup and double-click it. The editor goes grey. A few minutes later you get either the file or a crash report. Below: why that happens, and what works at 100 MB, 500 MB and 1 GB, with commands you can paste.
Start by deciding what you want from the file. Looking at it needs a viewer that doesn't build everything at once. Pulling data out of it needs a streaming parser or jq.
A settings file or a small export doesn't need any of this. For those, how to open a JSON file covers Notepad, TextEdit, browsers, VS Code, Excel and phones.
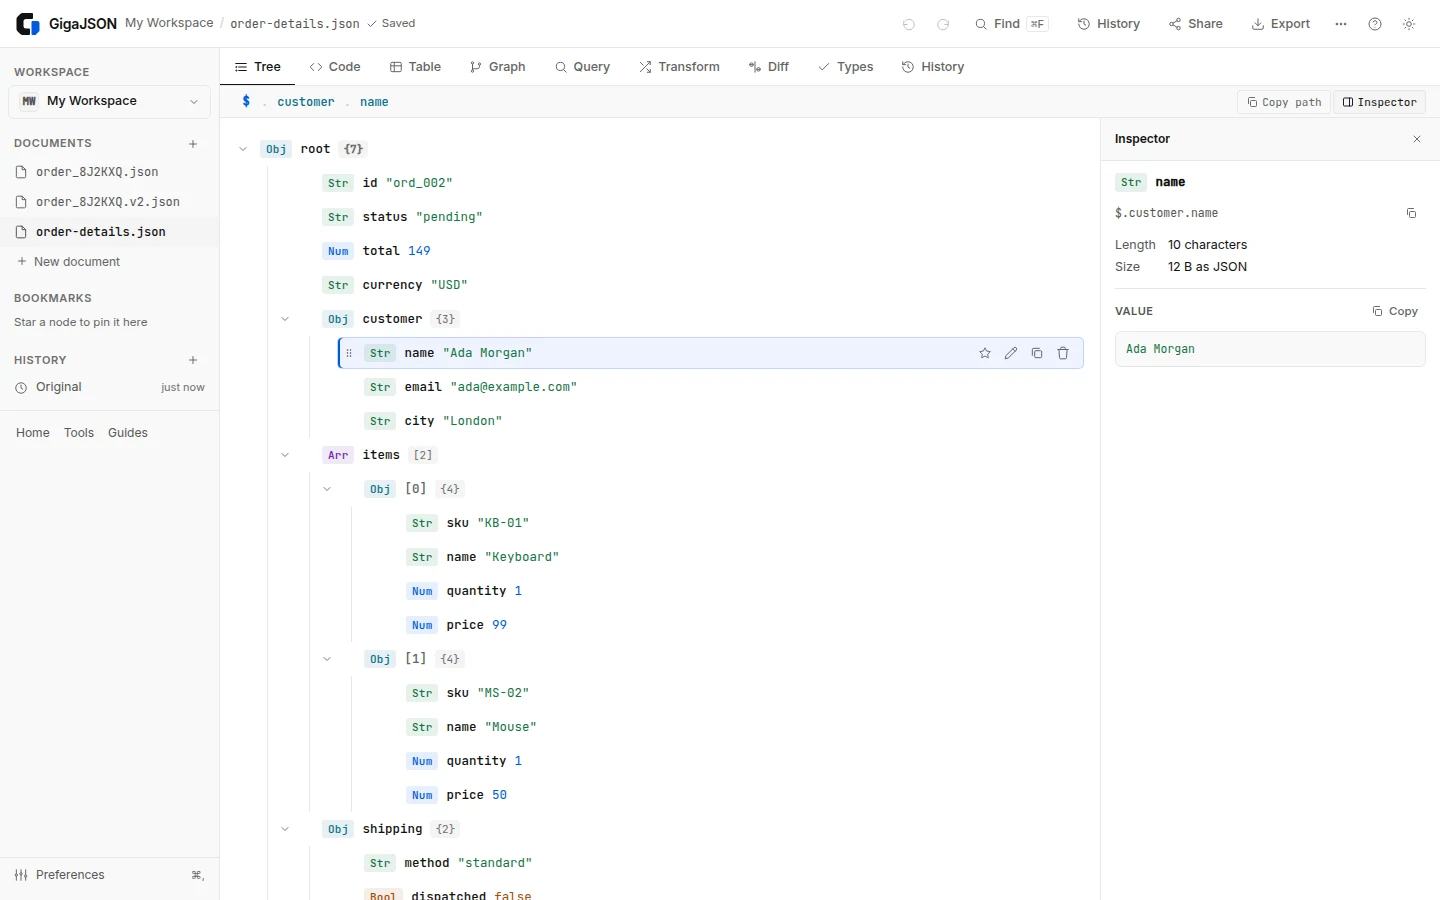
Open a large JSON file in your browser, step by step
- Go to the large JSON viewer. You install nothing, and the file stays on your computer.
- Choose Open file and pick the file. A background worker reads it (up to 1 GB), and the page keeps responding.
- Wait for the tree. On our test laptop, 200 MB takes about 2 seconds, 500 MB about 9 and 1 GB about 18 (benchmarks).
- Open the branch you care about. For a list of records, switch to Table to sort and filter.
- Find searches keys and values. Query runs JSONPath and JMESPath; jq works on files up to about 20 MB.
- To edit, choose Open in GigaJSON. Files over 512 MB need Preferences → Largest document set to 1 GB first.
If you'd rather stay in a terminal or in Python, keep reading.
Why editors choke on big JSON
You hit three limits, usually in this order.
The parsed tree is much bigger than the file
JSON text is compact. Parse it, and each object, key and number becomes its own allocation with its own overhead. I measured this on a 15.5 MB file of 200,000 small orders (Intel i5-9300H, Linux):
| Tool | Peak memory | Time |
|---|---|---|
jq '.orders | length' |
231 MB | 0.6 s |
Python json.load |
142 MB | |
Node JSON.parse |
104 MB | |
jq --stream (filter shown below) |
3.6 MB | 6.0 s |
Python ijson.items |
14 MB | 0.4 s |
Plain jq needed about 15 times the file size. At that ratio, a 1 GB file wants well over 10 GB of RAM. The streaming parsers stay flat because they hold one item at a time.
Text editors try to highlight and fold everything
On top of parsing, an editor tokenizes the text for colours, works out folding ranges and runs a language server to validate it. VS Code turns these features off for big files. Its source puts the cut-off at 20 MB or 300,000 lines, and past 50 MB it stops syncing the file to extensions, so you lose JSON validation and the outline. Scrolling a few hundred megabytes of single-line JSON is still slow after all that. Minified JSON, one enormous line, is the worst case for any text editor.
Browsers have a hard string limit
Chrome won't create a JavaScript string longer than 536,870,888 characters (about 512 MB). A web tool that calls file.text() and then JSON.parse stops there, however much RAM you have. You'll see "Invalid string length" or "Cannot create a string longer than 0x1fffffe8 characters". And if the parse runs on the page's main thread, the tab freezes until it finishes.
First: look at the file without opening it
Check what's inside before you choose a tool. These two commands read only the start of the file:
ls -lh export.json          # how big is it really
head -c 2000 export.json    # the first 2 KB: is it one array, an object, NDJSON?
One JSON object per line means you have NDJSON (JSON Lines), and your life gets easier. head, grep, split and wc -l all work on it, and any tool can read it line by line. Viewing and querying NDJSON logs covers that case.
For one big document, note the top-level shape. Most large files look like {"meta": ..., "items": [ ...millions of things... ]}, and the path to the big array (items here) is what you'll stream over.
Option 1: jq, when the machine has the RAM
If the file fits in memory, jq answers a question faster than anything else. Some commands I use all the time:
jq '.orders | length' big.json                 # how many items
jq -c '.orders[:2]' big.json                   # the first two items, compact
jq 'keys' big.json                             # top-level keys
jq -c '.orders[] | select(.status == "refunded") | .id' big.json > refunded.txt
Memory is the problem. Going by the table above, plan for 10 to 20 times the file size: fine for 300 MB on a 16 GB laptop, probably not for 1 GB.
Option 2: jq --stream, slow but constant memory
With --stream, jq emits path/value events and never builds the document. Add fromstream and truncate_stream and you can rebuild one array element at a time:
jq -cn --stream '
  fromstream(2 | truncate_stream(inputs | select(.[0][0] == "orders")))
  | select(.status == "refunded")
  | .id' big.json
The 2 is how many path levels to strip. ["orders", 17, "status"] becomes ["status"], so jq rebuilds each order as a standalone object. For a bare top-level array, drop the select and strip one level: jq -cn --stream 'fromstream(1 | truncate_stream(inputs))' big.json.
On the 15.5 MB test file this took 6.0 s and 3.6 MB of memory. Plain jq took 0.6 s and 231 MB. So you pay ten times the time for a sixtieth of the memory, and for a multi-gigabyte file on a small machine you have no other way.
Option 3: a streaming parser in Python or Node
When the job is to go through every record and compute something, ten lines of code with a streaming parser will do it.
Python with ijson
pip install ijsonimport ijson
from decimal import Decimal
refunded = 0
total = Decimal(0)
with open("big.json", "rb") as f:
for order in ijson.items(f, "orders.item"):
if order["status"] == "refunded":
refunded += 1
total += order["total"]
print(refunded, total)"orders.item" means each element of the orders array; for a file that is a bare array, use "item". ijson hands back decimal numbers as Decimal, which is why the total starts as one. When the fast C backend (yajl2_c) is installed, ijson uses it. In my test it beat json.load on time and used a tenth of the memory.
Node with stream-json
Node ships without a streaming JSON parser. The stream-json package fills that gap:
npm install stream-jsonconst fs = require('fs');
const { chain } = require('stream-chain');
const { parser } = require('stream-json');
const { pick } = require('stream-json/filters/Pick');
const { streamArray } = require('stream-json/streamers/StreamArray');
let refunded = 0;
chain([
fs.createReadStream('big.json'),
parser(),
pick({ filter: 'orders' }),
streamArray(),
])
.on('data', ({ value }) => { if (value.status === 'refunded') refunded++; })
.on('end', () => console.log(refunded));I tested this with stream-json 1.9.1. It runs slower than ijson's C backend, but file size doesn't matter to it. JSON.parse(fs.readFileSync(path, 'utf8')) on a 1 GB file fails at the string limit before parsing even begins.
Option 4: load it into a database
Planning to ask the same file many different questions? Import it once. DuckDB reads JSON and NDJSON with read_json_auto, and SQLite has JSON functions. You wait for the import one time, and after that you get SQL and fast queries. For analysis that goes on for days, I'd pick this. For a one-off look it's too much setup.
Option 5: split it into smaller files
If a colleague needs the data in a tool with a size limit, split it. jq streams it into NDJSON and split cuts that into parts:
jq -cn --stream 'fromstream(2 | truncate_stream(inputs | select(.[0][0] == "orders")))' big.json > orders.ndjson
split -l 100000 orders.ndjson part_
Each of part_aa, part_ab and so on holds 100,000 records, one per line. To turn one back into a JSON array: jq -s . part_aa > part_aa.json.
Option 6: a viewer that parses off the main thread
Sometimes you only want to look: scroll the structure, search for an ID, see what record 1.2 million looks like. A viewer suits that if it gets three things right. It parses in a background thread (a Web Worker, in a browser) so the window stays usable. It keeps the parsed data away from the interface and draws only the rows on screen. And it reads the file in pieces, never as one string.
GigaJSON is a browser tool built on those rules. Open a file in the large JSON viewer or the full app and a worker parses it on your machine; nothing gets uploaded. We benchmarked it on the same i5-9300H laptop in Chrome: the tree appeared after 2.1 s for 200 MB, 9.3 s for 500 MB and 18.3 s for 1 GB (medians of three runs, October 2026), and the page kept responding throughout. The page's own heap stayed between 5 and 7 MB at every size, since it only ever receives the rows on screen. That figure leaves out worker memory, so it isn't the total footprint. The benchmark page has the three raw runs, exact byte counts and a fixture generator; those archived reports don't record the exact source revision.
Once the file is open you can browse the tree, see an array of objects as a table, search with Find, and run JSONPath or JMESPath. The limits you should know about:
- The largest-document setting starts at 512 MB. Raise it to 1 GB in Preferences.
- At 1 GB the worker needs a few GB of RAM. On an 8 GB machine with other apps open, close some tabs first.
- Queries over the whole document are slow at that size:
$..skuover the 1 GB file took about a minute. - jq in the browser stops at about 20 MB of input (the WebAssembly build aborts past ~25 MB). For big files, use JSONPath or JMESPath in the browser, or jq in a terminal.
- Native desktop viewers open 1 GB files much faster than a browser tool can. If you open giant files every day, that speed may matter more to you than skipping an install.
- GigaJSON keeps the file in the browser's storage so you can come back to it. That costs about twice the file size on disk (the document plus its "Original" version).
Which option to pick
| You want to... | Use |
|---|---|
| Answer one question, file fits in RAM | jq |
| Process every record of a multi-GB file | ijson (Python) or stream-json (Node) |
| Same, without writing code, on a small machine | jq --stream |
| Ask many questions over days | DuckDB or SQLite |
| Hand the data to someone with a size limit | split into NDJSON parts |
| Browse, search and inspect up to 1 GB | a viewer that parses in a worker, such as the large JSON viewer |
If you control how the file gets written, write NDJSON instead of one giant array. Every tool on this list handles it better, and so does grep.